
GenAI Marketing Benchmarks
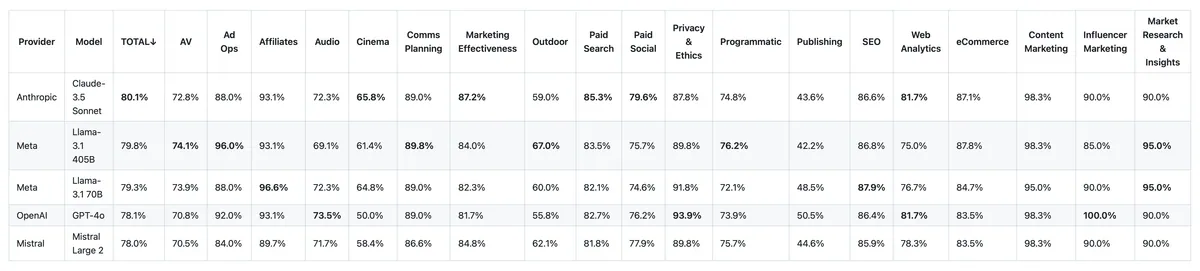
A research project to assess and compare the marketing knowledge of large language models, addressing a gap in the benchmarks available at the time.
Sole developer · June–December 2024View on GitHub (opens in a new tab)
What it does
- Assess marketing knowledge through a database of multiple-choice questions.
- Run automated evaluations across models from different providers.
- Compare model results against a common set of marketing questions.
- Adjust evaluation criteria as the benchmark develops.
The challenge
There were benchmarks for many areas of knowledge, but I could not find a way to judge how well LLMs understood marketing. I started this project to fill that gap, building a question database and tools to test models against it. The challenge was deciding what a useful assessment of marketing knowledge should cover and getting wider industry participation in developing it.
What I learned
The project ran out of steam when I could not get enough engagement from the wider UK marketing industry. Building the evaluation tools was only part of the work. A benchmark also needs people to help shape it, challenge its assumptions and use its results. I had underestimated how much the project's momentum would depend on that participation.
Built with
- Python
- SQLite
- OpenAI API
- Anthropic API
- Google AI API
- Together AI
- AI Harness
- pandas
- matplotlib
- Flask